Lecture 3
Recap last week:
- TF.IDF
- BM25
- Language modeling - query likelihood
A language models assigns a probability to a sequence from words, that is drawn from the underlying probability distribution over the whole vocabulary.
Query Likelihood Model
Relevance assumption: approximates relevance with P(q|d, R=1).
Let's take the unigram version where terms are assumed to be independent.
Then $P(q|d)=\prod_{i=1}{n}P(q_i|M_d)$.
But... how do we know the document language model $M_d$? We make a simple assumption that we can get that model $P(q_i|M_d)$ with MLE: $\frac{c(q_i,d)}{|d|}$ (n.b. enumerator is just the TF term).
Example
q: "Apple Phone"
- Apple Samsung
- 1/2 x 0 = 0
- Apple Apple Apple Samsung
- 3/4 x 0 = 0
- Phone Samsung Phone Apple Phone Apple Samsung
- 2/7 x 3/7 = 6/49
Clear issue: a document needs to have all query terms to show up other than zero. But this is not desirable for many reasons, one being spamming all words will then receive a higher score. Long documents receive a very low probability as well. Also not robust against queries that are not that well formulated. In sum, really shitty!
Jelinek-Mercer (JM) Smoothing
To solve the previous examples: assign non-zero probabilities to words that are not observed in the data.
Interpolation: smoothing the probability coming from the document with the probabilities from the whole collection. This is usually done linearly.
We weigh document frequency with (1-lambda), the background model over the whole collection with lambda. In the MLE formula, we of course now use the document length in the first case, collection length in the latter; otherwise the counts will not be properly normalized into probabilities.
$$P(q|d) \approx \prod_i^n (1-\lambda) \frac{ c(q_i,d)}{|d|} + \lambda \frac{c(q_i, c)}{|C|}$$
With large lambda, the background model is weighed more. For lower lambda, we have more specificity.
In the previous example we again used TF. Smoothing employs a similar logic as the inverse document frequency used in TF.IDF! Just like IDF relates a word to its occurrence in the corpus, just so do we now compute something similar with $P(w|C)$
This solves the problem with zero probabilities: because a word occurs in the vocabulary (by definition, in an ideal scenario), it will always have a non-zero probability.
What if even then a query term is not in the vocabulary? Usual strategy: ignore that query term.
What's a good choice for lambda? Similar to other machine learning approaches, you determine this using a train, validation and test set.
Dirichlet smoothing
JM-Smoothing uses a fixed smoothing coefficient. We apply the same ideas, but now use a dynamic smoothing coefficient to interpolate (still linear though!). Dynamic because it depends on the length of the given document.
Now replace "1-lambda" with $\frac{|d|}{|d|+\mu}$ and lambda with $\frac{\mu}{|d|+\mu}$. Note that they both sum up to 1 all the same.
$$P(q|d) = \prod_{i=1}^n \frac{|d|}{|d|+\mu} \dot \frac{c(q_i, d)}{|d|} + \frac{\mu}{|d|+\mu}\dot\frac{c(q_i,C)}{|C|}$$ $$=\prod_{i=1}{n}\frac{c(q_i,d)+\mu*P(q_i|C)}{ |d| + \mu }$$
N.B. $\mu \in [0, \infty)$
In the second formulation it is easy to understand this as if every word w has $\mu \dot p(w|C)$ pseudo-counts. (That's also why we add $\mu$ in the denominator to normalize given the pseudo-counts).
Again: the left part captures the "TF" logic, the right part captures the "IDF" logic.
This effectively rewards shorter documents according to the slides, but it's not clear to me what this means.
Q: Why can one say that Dirichlet Smoothing reward shorter documents?
A long document has relatively less smoothing, which makes sense (because the shorter the document, the more prominent the zero probability problem will be). Instead if |d| is small, then the background model gains more weight (the proportion of pseudo-counts relative to the document length grows ).
If we plug this smoothing function into the query likelihood function (see Zhai, p.121), then we get a formula (see Zhai p.127) that puts relatively more "mass" onto short documents. This means that this inherently does document length normalization.
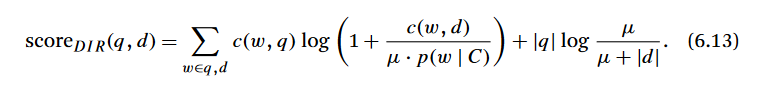
Q: In what way does the Query Likelihood model inherently include TF-IDF weighting and document length normalization?
Prevent computational underflow
Instead of multiplying the probabilities, we take the sum of the log instead. But note that this way we will get negative scores.
For ranking, we don't need to negate that. We just need to sort in reverse order for the ranking.
Fielded Retrieval Models
Take a structured HTML document.
Perhaps you want to give more weight to the terms in the title.
How to do so?
We can do the previous computations for each document part, and then combine them with additional weighing factors. This would be the "meta-search" strategy from the background reading of this week. Cf. Ogilvie_and_Callan-Combining_Document_Representations_for_Known-Item_Search.md .
Instead, we can also do a Mixture of Language Models (MLM) where we assign each field a weighted Language Model.
First we had the language model:
$P(q|d)~=\prod_{i=1}{n}P(q_i|M_d)$
Fielded variant (with JM-smoothing):
$P(q|d)~=\prod_{i=1}^n \sum_{f=F}P(q_i|M_{d_f})$
So here we still have a single model, but one that factors in the fields of a structured document.
BM25F
Fielded BM25: BM25F.
BM25 involves some heuristics and some probabilistic assumptions. (Main difference with language modeling is that the latter is more principled).
This is basically a MLM where we have a separate language model per each field.
Discussed in optional reading (that I did not read). This article argues that in BM25F it is sufficient (and in some ways desirable) to only use the TF for fields.
- Combines the term frequencies of the different fields using a weighted linear combination
- Weights corresponds to fields weights
- No use of field collection statistics
- For short fields (such as title) these statistics may be unstable
- Avoids too many parameter tuning.
See slide for BM25 formula with "transferred" term frequency.
$$score(q,d)=\sum_{i=1}^n \frac{ (k+1)c(q_i,d)}{k(1-b+b \frac{|d|}{avdl}) + c(q_i,d)} idf(q_i)$$
BM25F:
$$score(q,d)~=\sum_{i=1}^n \frac{ (k+1)c'(q_i,d)}{k + c'(q_i,d)} idf(q_i)$$
where c' is now a computation that takes fields into account, and $\alpha$ is the smoothing parameter (for example $\mu$).
Not sure I copied this one correctly! $c'(q_i,d) ~= \sum_{f \in F}(1-b_f+b_f \frac{|f_d|}{avfl})$
Notice that now we do not take the average document length but the average field length! That is, the "collection statistics" or background model is now defined per field.
All computations are estimations because we only care about ranking, rather than having the correct probabilities.
Q: Does BM25F (fielded) usually also have a IDF-like term?